AI Application Data Security: A Practical Guide for 2026
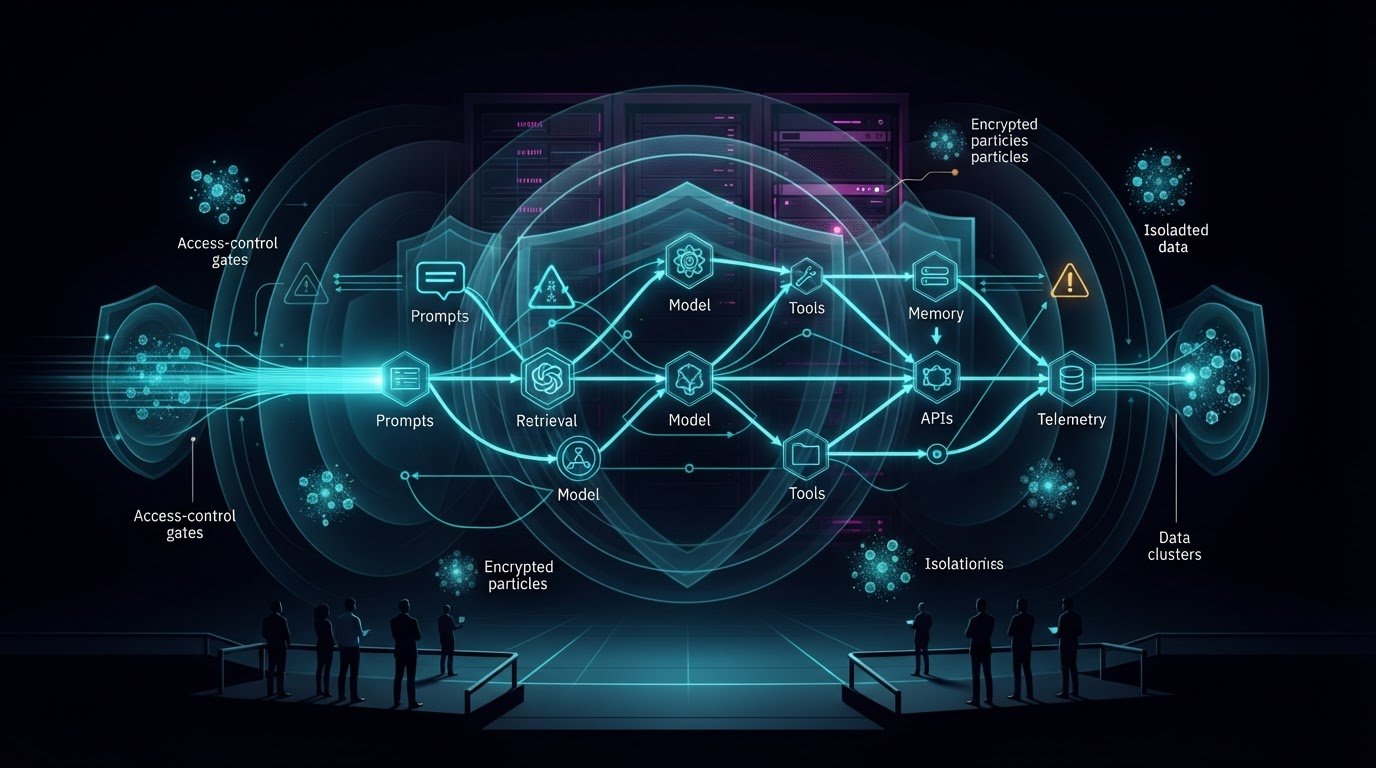
An AI application can run on infrastructure you control and still expose sensitive data through a prompt, tool call, memory store, or debug log. AI application data security is a full-path problem, not a box to check by choosing where the model runs.
It’s reasonable to focus on the model provider or deployment environment, but those choices protect only part of the system. User inputs can pass through connected services, agent memory, APIs, and logs, each with its own trust boundary and exposure risk. Self-hosting gives you control over where a component runs and stores data, but it doesn’t secure every handoff or establish compliance.
This guide maps where information can surface across an AI application, shows how to identify sensitive data and trust boundaries before deployment, and matches practical controls to risks. You’ll also learn what to check when evaluating providers and infrastructure. The goal is a security plan built around the entire data path, including prompts, outputs, tools, memory, and logs.
Key Takeaways
- Inventory prompts, files, outputs, memory, credentials, and telemetry so sensitive data doesn’t fall outside your governance plan.
- Trace a request through retrieval, model processing, tools, and retention to find weak access boundaries and disclosure risks.
- Compare managed, self-hosted, and hybrid designs by data location and operator responsibility, not by broad security claims.
- Make AI application data security actionable by assigning controls to identified risks, testing them, and reviewing access over time.
- Treat NovaCortex Self-Hosted Edition as a memory layer within a wider design. Local storage doesn’t replace access, network, backup, or retention controls.
AI application data security starts with mapping what the application handles
Start with the data, not the model. AI application data security is the set of technical and operational controls that protect information as an application collects, processes, transmits, stores, and deletes it. A privacy policy explains how information is handled and communicated to users. Regulatory compliance concerns whether applicable requirements are met. Neither, by itself, secures the application’s data paths.
Exposure depends on several layers. Model-provider terms describe how a provider handles requests, while application design determines what information is sent and which components receive it. Deployment controls govern the infrastructure you operate. Assess each layer separately rather than treating a provider choice or self-hosted deployment as proof that the whole application is secure.
Which data moves through an AI application?
Trace one request from start to finish. A user submits a prompt or file, the application retrieves relevant knowledge, sends a model request, receives a response, and may pass information to a tool. Tool outputs can then re-enter the model context or appear in the user-facing result.
Inventory more than the visible conversation. Include agent memory, observability systems, error reports, caches, and backups. For each data type, record sensitive fields, where the data travels, who or what can access it, and whether it needs to be collected or retained. Treat credentials and tokens separately: don’t place them in prompts or persistent context. Collecting and retaining less data means fewer copies and locations to secure.
Where are the trust boundaries?
Draw boundaries between the user interface, application backend, model API, data stores, and external tools. Mark which components your organization operates and which rely on third parties. At every handoff, ask what data crosses, which identity authorizes access, and what records may be created or retained. This makes risks such as excessive permissions, accidental disclosure, and adversarial inputs easier to locate. Adversarial machine learning provides background on attacks including data poisoning.
Give memory its own boundary. A self-hosted AI memory layer can keep stored knowledge on infrastructure you control, but the surrounding application still determines what enters memory and which components can retrieve it. Map how memory fits into the larger architecture rather than treating local storage as a complete security measure. Then choose controls for the risks the map reveals.
Follow the AI data path to find exposure points and threats
A request doesn’t stop at the model. It may pass through retrieval, persistent memory, connected tools, monitoring systems, and backups before the interaction is complete. Trace the sequence: user submission, context retrieval, model processing, tool calls, response generation, and retention. At each step, record what data moves, which identity can access it, and what happens if the operation fails.
Every external integration adds a data boundary to assess. A model API may receive prompt content, a retrieval service may return records, a tool may read or modify data, and an observability pipeline may capture request details. For every handoff, check permissions, data handling, and potential exposure.
How prompts, retrieval, and memory create different risks
Before sending a prompt, check whether it contains personal information, confidential business content, or credentials. Remove or mask fields the model doesn’t need. Retrieval creates a separate authorization problem: the agent should receive only documents the requesting user is allowed to access. If search ignores user permissions, a relevant result can become an unintended disclosure.
Prompt injection can manipulate how a model interprets instructions or retrieved content. That’s a model and application behavior risk, distinct from conventional flaws such as weak access controls or an exposed API secret. Address both. Persistent memory adds another dimension: treat it as a governed data store with defined access and retention rules, not as invisible context.
How tools, logs, and integrations widen the attack surface
For every connected tool, document what the agent can read, write, or execute on the agent’s behalf. Scope permissions to the task. A summarization workflow shouldn’t inherit permission to send messages or modify records unless those actions are necessary. Review tool outputs, too, because returned content may influence later model decisions.
Inspect what enters logs and monitoring pipelines. Prompts, generated responses, user identifiers, tool results, and secrets can be copied into traces or error reports, creating secondary data stores with their own access and retention risks. The NIST AI Risk Management Framework offers a structured way to map and manage AI risks alongside application-level reviews.
If memory communicates through MCP, assess the protocol connection and server permissions as part of the same data path. Teams evaluating a self-hosted memory layer can review the NovaCortex project repository for deployment context, then verify which controls their own configuration requires.
Compare AI application security controls by data boundary
There’s no universally safest deployment model. A managed model API can reduce the infrastructure your team operates, while a self-hosted component can give you more control over where data resides. A hybrid design may keep memory or retrieval in your environment while sending selected requests to an external model. Compare the boundaries each option creates, then assign responsibility for the controls on both sides. That’s the practical basis of AI application data security.
| Design | Data location | Operator responsibility | Access control | Retention | Integration exposure |
|---|---|---|---|---|---|
| Managed model API | Requests reach a provider’s service. | Review provider controls and secure your application and credentials. | Limit who and what can call the API. | Verify provider terms and settings. | Assess each API and connected service. |
| Self-hosted components | Components can run on infrastructure you control. | Operate and secure the deployment, including patching and monitoring. | Configure and review identities and permissions. | Set and enforce your own retention rules. | Secure the model, storage, network, and tools. |
| Hybrid design | Data is split across local and third-party systems. | Coordinate controls across every operator. | Enforce permissions at each handoff. | Track retention in every system. | Map and test the full chain of integrations. |
What self-hosting changes, and what it leaves to you
Self-hosting can increase control over infrastructure and where application data is stored. It doesn’t remove the work of patching components, managing identities, setting network boundaries, protecting backups, or monitoring activity. Local deployment, open-source licensing, and data residency don’t prove security or compliance. Evaluate the actual configuration and operational controls.
Encryption in transit and at rest can protect data across network links and storage media, but don’t stop at a feature claim. Verify where encryption applies, how keys are generated and managed, and who can access them. The OWASP Top 10 for LLM Applications can help identify AI-specific threat categories to consider when selecting controls.
Assess providers and obligations
For each model or connected service, document the data it receives. Review current provider documentation and contractual terms for retention, training use, deletion, and incident response. These details can change, so verify them before deployment and during reviews. Data portability matters too: a portable memory format can make it easier to move stored knowledge between systems, but portability alone doesn’t secure that data.
Keep technical safeguards distinct from governance frameworks and law. NIST AI RMF helps structure risk management; it isn’t a security control or legal obligation. GDPR, where it applies, is a legal framework, not an encryption setting. A sound design uses technical controls to reduce specific risks, governance to track them, and qualified review to determine which legal requirements apply.
Build an AI application data security checklist before deployment
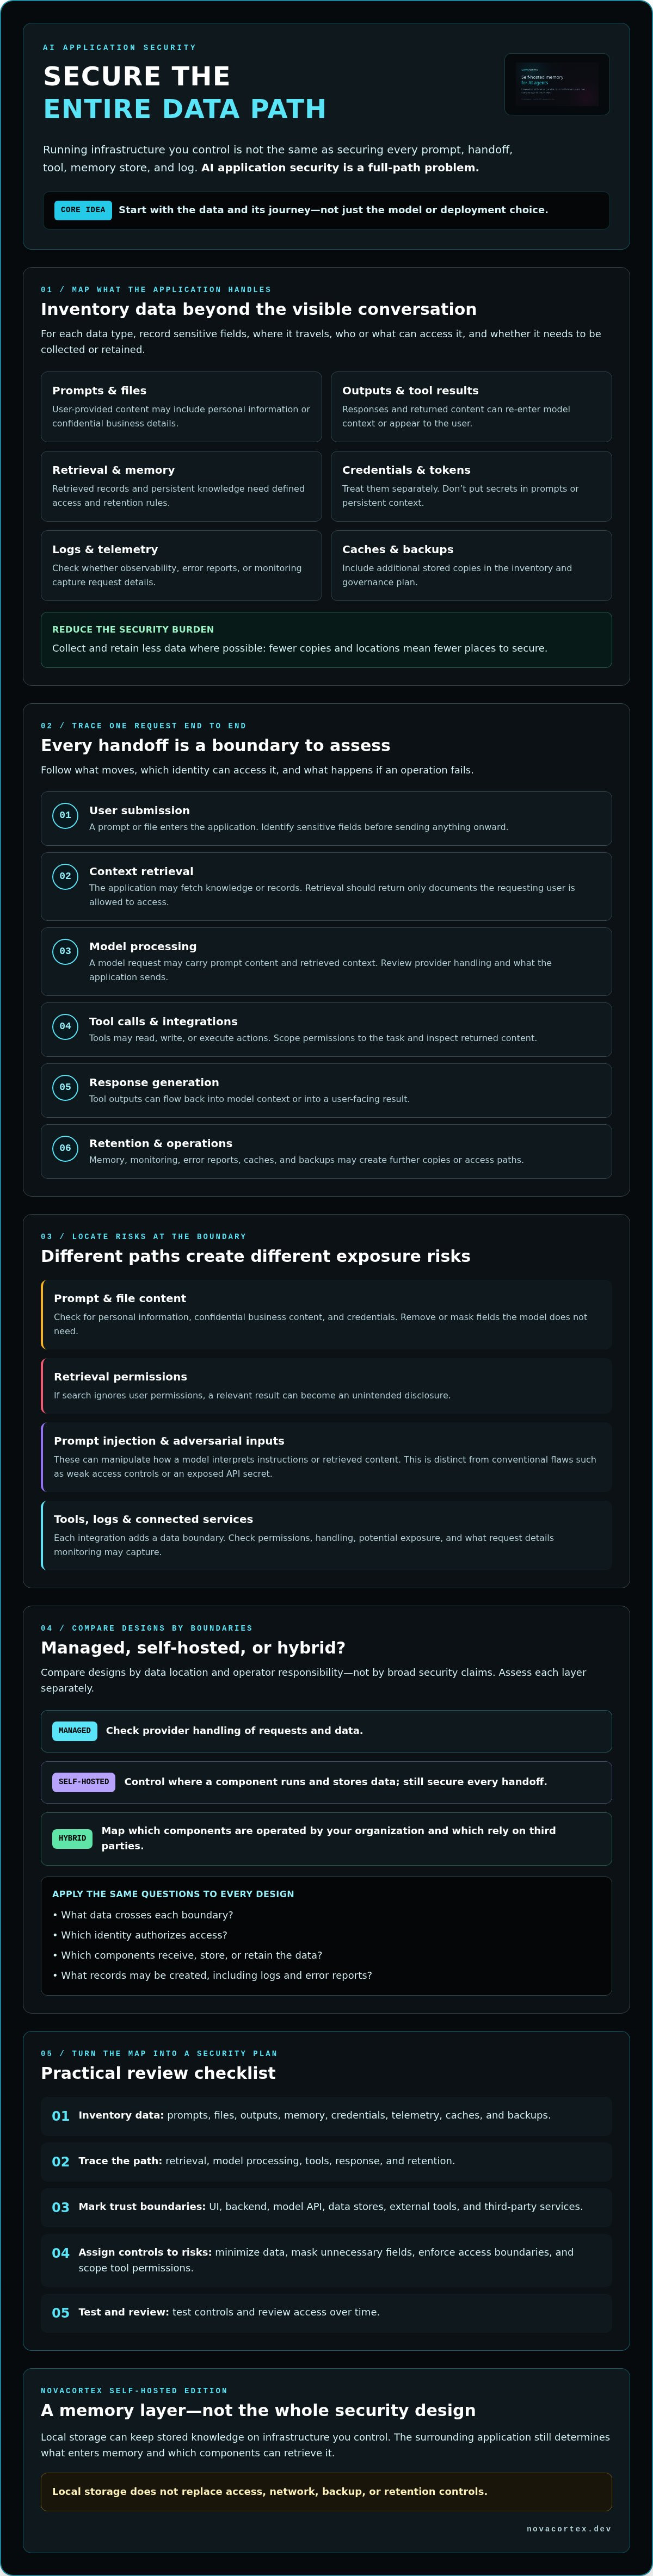
A checklist helps only when each item has an owner, evidence, and a test. Use this workflow to turn your data-flow map into implementation tasks, then revisit it whenever the model, tools, or deployment changes. This makes AI application data security an ongoing engineering practice rather than a launch-day sign-off.
- 1. Inventory data. List prompts, files, outputs, memory, credentials, and telemetry, including copies in logs, caches, and backups.
- 2. Map flows. Record where each data type goes, which component handles it, and whether that component is operated by your organization or a third party.
- 3. Classify risks. Identify sensitive fields, unauthorized access paths, unnecessary collection, and retention that exceeds the application’s needs.
- 4. Assign controls. Use least-privilege identities, scoped tool permissions, secrets management, and access reviews where applicable. Define retention limits, deletion procedures, backup protections, and an incident owner.
- 5. Test and document. Verify that controls work, record results and gaps, and assign owners and follow-up actions.
- 6. Monitor and review. Track relevant access and configuration changes, then reassess the design after significant changes to models, tools, data sources, or deployment.
Verify development and testing
Test authorization with normal, elevated, and adversarial requests using synthetic or approved test data. Confirm that retrieval and connected tools enforce the same user permissions as the application, including when someone attempts to access another user’s records. Inspect logs and error paths for prompts, outputs, identifiers, or credentials that may be stored unexpectedly. Record what passed, what failed, and how each gap will be addressed.
Assign operational ownership
Before release, name owners for dependency updates, access reviews, incident handling, and security configuration changes. Monitor unexpected access patterns and changes in data flows while limiting sensitive telemetry to what’s needed for investigation. Set a review trigger for new integrations or changes in deployment responsibility. A self-hosted component shifts some operational work to your team; a managed service shifts other responsibilities to its provider. Document the division instead of assuming it.
For a self-hosted memory component, review the project’s documented deployment details and assess how they fit your controls and responsibilities. You can start with the NovaCortex repository.
Use NovaCortex self-hosted memory as one layer in a wider security design
A memory layer can change where persistent agent knowledge is stored. It doesn’t secure every path that feeds, retrieves, or acts on that knowledge. Treat NovaCortex as a self-hosted memory layer within your application architecture, not as a complete application security product. Its open-source Apache-2.0 license, Portable Memory Format, and graph-native storage are architectural attributes, not proof of security or compliance.
Place memory in the data flow
Add the memory component to your data-flow diagram. Identify which users or agents can interact with it, what information enters, what context it returns, and which services or infrastructure it depends on. For example, determine whether retrieved knowledge is passed to a model, an external tool, or both, and how application authorization governs those requests.
Local storage on infrastructure you control can give you control over the memory deployment boundary. The surrounding environment still needs to meet your requirements for access management, network controls, monitoring, backup protection, and recovery. Define who operates each control and how you’ll verify it. A server, VPS, or other deployment location doesn’t automatically provide those protections.
Evaluate the actual deployment
Before adoption, review the repository, license, deployment instructions, and current configuration guidance. Verify documented behavior before attributing authentication, authorization, encryption, logging, backup, or retention features to NovaCortex. Then test the intended setup against your threat model: check who can read or modify memory, how data is protected in transit and at rest, how changes are monitored, and what happens during restoration or deletion.
Portable memory can reduce dependence on a single storage format or vendor, but portability isn’t a substitute for governance. Decide what belongs in persistent memory, how long it should remain, and how access is reviewed. Treat these as application-level design decisions that must fit your operational requirements.
In practice, the right question isn’t simply “Is this self-hosted?” It’s whether the selected configuration gives your team an acceptable, testable way to manage its part of the data path. Compare the project’s current documentation with your deployment and security requirements before integrating it. The NovaCortex project on GitHub is a place to begin that review.
Make the Full Data Path Your Starting Point
Strong AI application data security starts with knowing what information the system handles, where it travels, and which components can access it. Map the full path from user input through retrieval, models, tools, memory, and logs. Then match controls to each boundary instead of assuming one provider or deployment choice secures everything.
Turn that map into a working plan: limit permissions, test authorization and error paths, define retention and deletion, and assign owners for ongoing reviews. A self-hosted component can give you more control over where data is stored, but it still needs to fit your organization’s access, network, backup, and monitoring practices.
NovaCortex is an open-source memory layer under Apache-2.0, with memory stored on your infrastructure and a Portable Memory Format designed to avoid vendor lock-in. Its graph-native storage is designed to reduce token use by up to 98% compared with sending an entire knowledge base. These attributes may suit some architectures, but they don’t replace application-wide safeguards. Review the project against your threat model and operational requirements.
Build from evidence, test each boundary, and keep refining the design as your AI application evolves. That’s how security becomes part of the architecture, not an afterthought.
Frequently Asked Questions
Is self-hosting an AI application enough to make its data secure?
No. Self-hosting can give you more control over infrastructure and where data is stored, but it doesn’t automatically secure the application. Your team still needs to manage access, patching, network boundaries, backups, monitoring, and retention. Prompts may also go to external model APIs, and tools or logging services may be operated by third parties. Map every component and verify the controls in the actual deployment.
Can AI applications expose sensitive data through prompts or logs?
Yes. Prompts can contain personal details, confidential content, or credentials, and applications may copy prompts or generated outputs into logs, traces, error reports, caches, or backups. Review what each system records and who can access it. Reduce exposure by sending only necessary information, keeping secrets out of prompts, limiting sensitive logging, and setting appropriate access and retention controls for stored records.
How do I protect data sent to an AI model?
Start by minimizing and classifying the data in each request. Remove fields the model doesn’t need, and keep credentials out of prompts. Check the provider’s current terms and documentation for data retention, training use, and deletion practices. Secure the application’s API credentials, restrict which services can make requests, and verify encryption and key management for relevant connections. Test the complete request path, not just the model endpoint.
What data should an AI application security review include?
Include user prompts, uploaded files, retrieved knowledge, model requests, generated outputs, tool results, agent memory, credentials, and telemetry. Track copies in logs, error reports, caches, and backups too. For each type, record where it moves, which components handle it, who can access it, and whether it needs to be collected or retained. Review third-party integrations and test that retrieval and tool access respect user permissions.
Does open-source software guarantee AI data security?
No. Open-source code can be inspected, but a license doesn’t prove that code is free of vulnerabilities or that a particular deployment is configured securely. Review the project’s code, dependencies, license, deployment instructions, and current security guidance. Then test the configuration against your threat model and maintain it with appropriate access controls, updates, monitoring, backups, and retention practices. Open-source licensing also doesn’t establish regulatory compliance.
What is the difference between AI data privacy and AI data security?
Privacy concerns what information is collected, why it’s used, who it’s shared with, and how long it’s retained. Security concerns the controls that protect information from unauthorized access, disclosure, alteration, or loss. They overlap, but they’re not interchangeable: a privacy policy doesn’t enforce technical protections, and strong security controls don’t determine whether a data practice is appropriate or meets applicable obligations.
Can a self-hosted AI memory layer prevent data leaks?
Not by itself. A self-hosted memory layer can keep stored knowledge on infrastructure you control, but leaks can still occur through prompts, incorrect retrieval permissions, connected tools, logs, network exposure, or backups. NovaCortex stores memory locally on the user’s infrastructure using a portable format, but you still need to assess the deployment’s access, network, backup, and retention controls as part of the wider application design.
Evaluate NovaCortex for your architecture: review the deployment guidance and project details in the NovaCortex repository, then test the configuration against your data-flow map and security requirements.
FAQ
Which data moves through an AI application?
Trace one request from start to finish. A user submits a prompt or file, the application retrieves relevant knowledge, sends a model request, receives a response, and may pass information to a tool. Tool outputs can then re-enter the model context or appear in the user-facing result. Inventory more than the visible conversation. Include agent memory, observability systems, error reports, caches, and backups. For each data type, record sensitive fields, where the data travels, who or what can access it, and whether it needs to be collected or retained. Treat credentials and tokens separately: don’t place them in prompts or persistent context. Collecting and retaining less data means fewer copies and locations to secure.
Where are the trust boundaries?
Draw boundaries between the user interface, application backend, model API, data stores, and external tools. Mark which components your organization operates and which rely on third parties. At every handoff, ask what data crosses, which identity authorizes access, and what records may be created or retained. This makes risks such as excessive permissions, accidental disclosure, and adversarial inputs easier to locate. Adversarial machine learning provides background on attacks including data poisoning. Give memory its own boundary. A self-hosted AI memory layer can keep stored knowledge on infrastructure you control, but the surrounding application still determines what enters memory and which components can retrieve it. Map how memory fits into the larger architecture rather than treating local storage as a complete security measure. Then choose controls for the risks the map reveals. A request doesn’t stop at the model. It may pass through retrieval, persistent memory, connected tools, monitoring systems, and backups before the interaction is complete. Trace the sequence: user submission, context retrieval, model processing, tool calls, response generation, and retention. At each step, record what data moves, which identity can access it, and what happens if the operation fails. Every external integration adds a data boundary to assess. A model API may receive prompt content, a retrieval service may return records, a tool may read or modify data, and an observability pipeline may capture request details. For every handoff, check permissions, data handling, and potential exposure.
Is self-hosting an AI application enough to make its data secure?
No. Self-hosting can give you more control over infrastructure and where data is stored, but it doesn’t automatically secure the application. Your team still needs to manage access, patching, network boundaries, backups, monitoring, and retention. Prompts may also go to external model APIs, and tools or logging services may be operated by third parties. Map every component and verify the controls in the actual deployment.
Can AI applications expose sensitive data through prompts or logs?
Yes. Prompts can contain personal details, confidential content, or credentials, and applications may copy prompts or generated outputs into logs, traces, error reports, caches, or backups. Review what each system records and who can access it. Reduce exposure by sending only necessary information, keeping secrets out of prompts, limiting sensitive logging, and setting appropriate access and retention controls for stored records.
How do I protect data sent to an AI model?
Start by minimizing and classifying the data in each request. Remove fields the model doesn’t need, and keep credentials out of prompts. Check the provider’s current terms and documentation for data retention, training use, and deletion practices. Secure the application’s API credentials, restrict which services can make requests, and verify encryption and key management for relevant connections. Test the complete request path, not just the model endpoint.
What data should an AI application security review include?
Include user prompts, uploaded files, retrieved knowledge, model requests, generated outputs, tool results, agent memory, credentials, and telemetry. Track copies in logs, error reports, caches, and backups too. For each type, record where it moves, which components handle it, who can access it, and whether it needs to be collected or retained. Review third-party integrations and test that retrieval and tool access respect user permissions.
Does open-source software guarantee AI data security?
No. Open-source code can be inspected, but a license doesn’t prove that code is free of vulnerabilities or that a particular deployment is configured securely. Review the project’s code, dependencies, license, deployment instructions, and current security guidance. Then test the configuration against your threat model and maintain it with appropriate access controls, updates, monitoring, backups, and retention practices. Open-source licensing also doesn’t establish regulatory compliance.
What is the difference between AI data privacy and AI data security?
Privacy concerns what information is collected, why it’s used, who it’s shared with, and how long it’s retained. Security concerns the controls that protect information from unauthorized access, disclosure, alteration, or loss. They overlap, but they’re not interchangeable: a privacy policy doesn’t enforce technical protections, and strong security controls don’t determine whether a data practice is appropriate or meets applicable obligations.
Can a self-hosted AI memory layer prevent data leaks?
Not by itself. A self-hosted memory layer can keep stored knowledge on infrastructure you control, but leaks can still occur through prompts, incorrect retrieval permissions, connected tools, logs, network exposure, or backups. NovaCortex stores memory locally on the user’s infrastructure using a portable format, but you still need to assess the deployment’s access, network, backup, and retention controls as part of the wider application design. Evaluate NovaCortex for your architecture: review the deployment guidance and project details in the NovaCortex repository, then test the configuration against your data-flow map and security requirements.