Cursor AI Memory Integration: Engineering Persistent Context with MCP
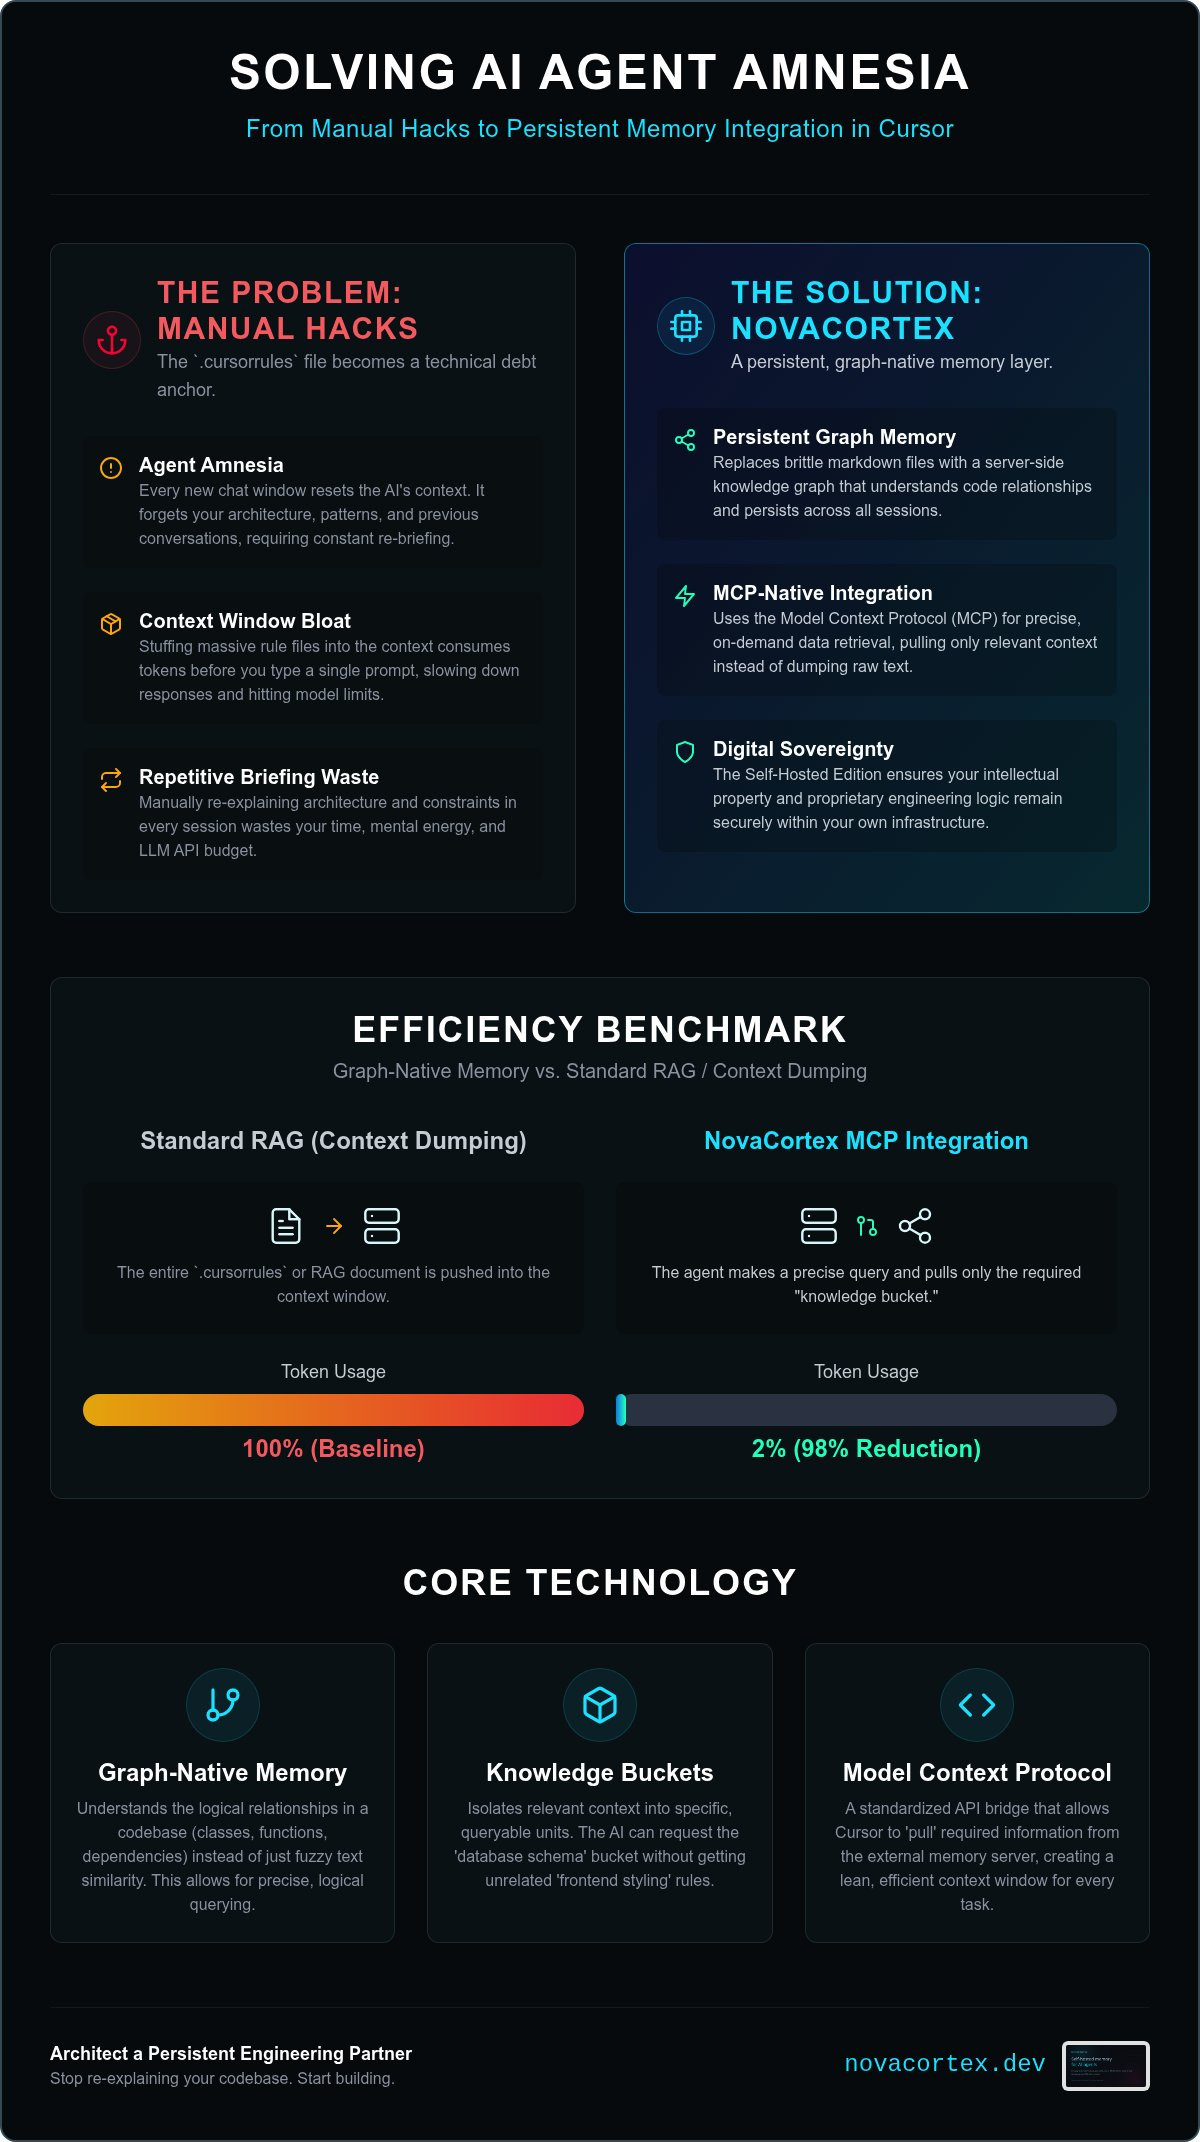
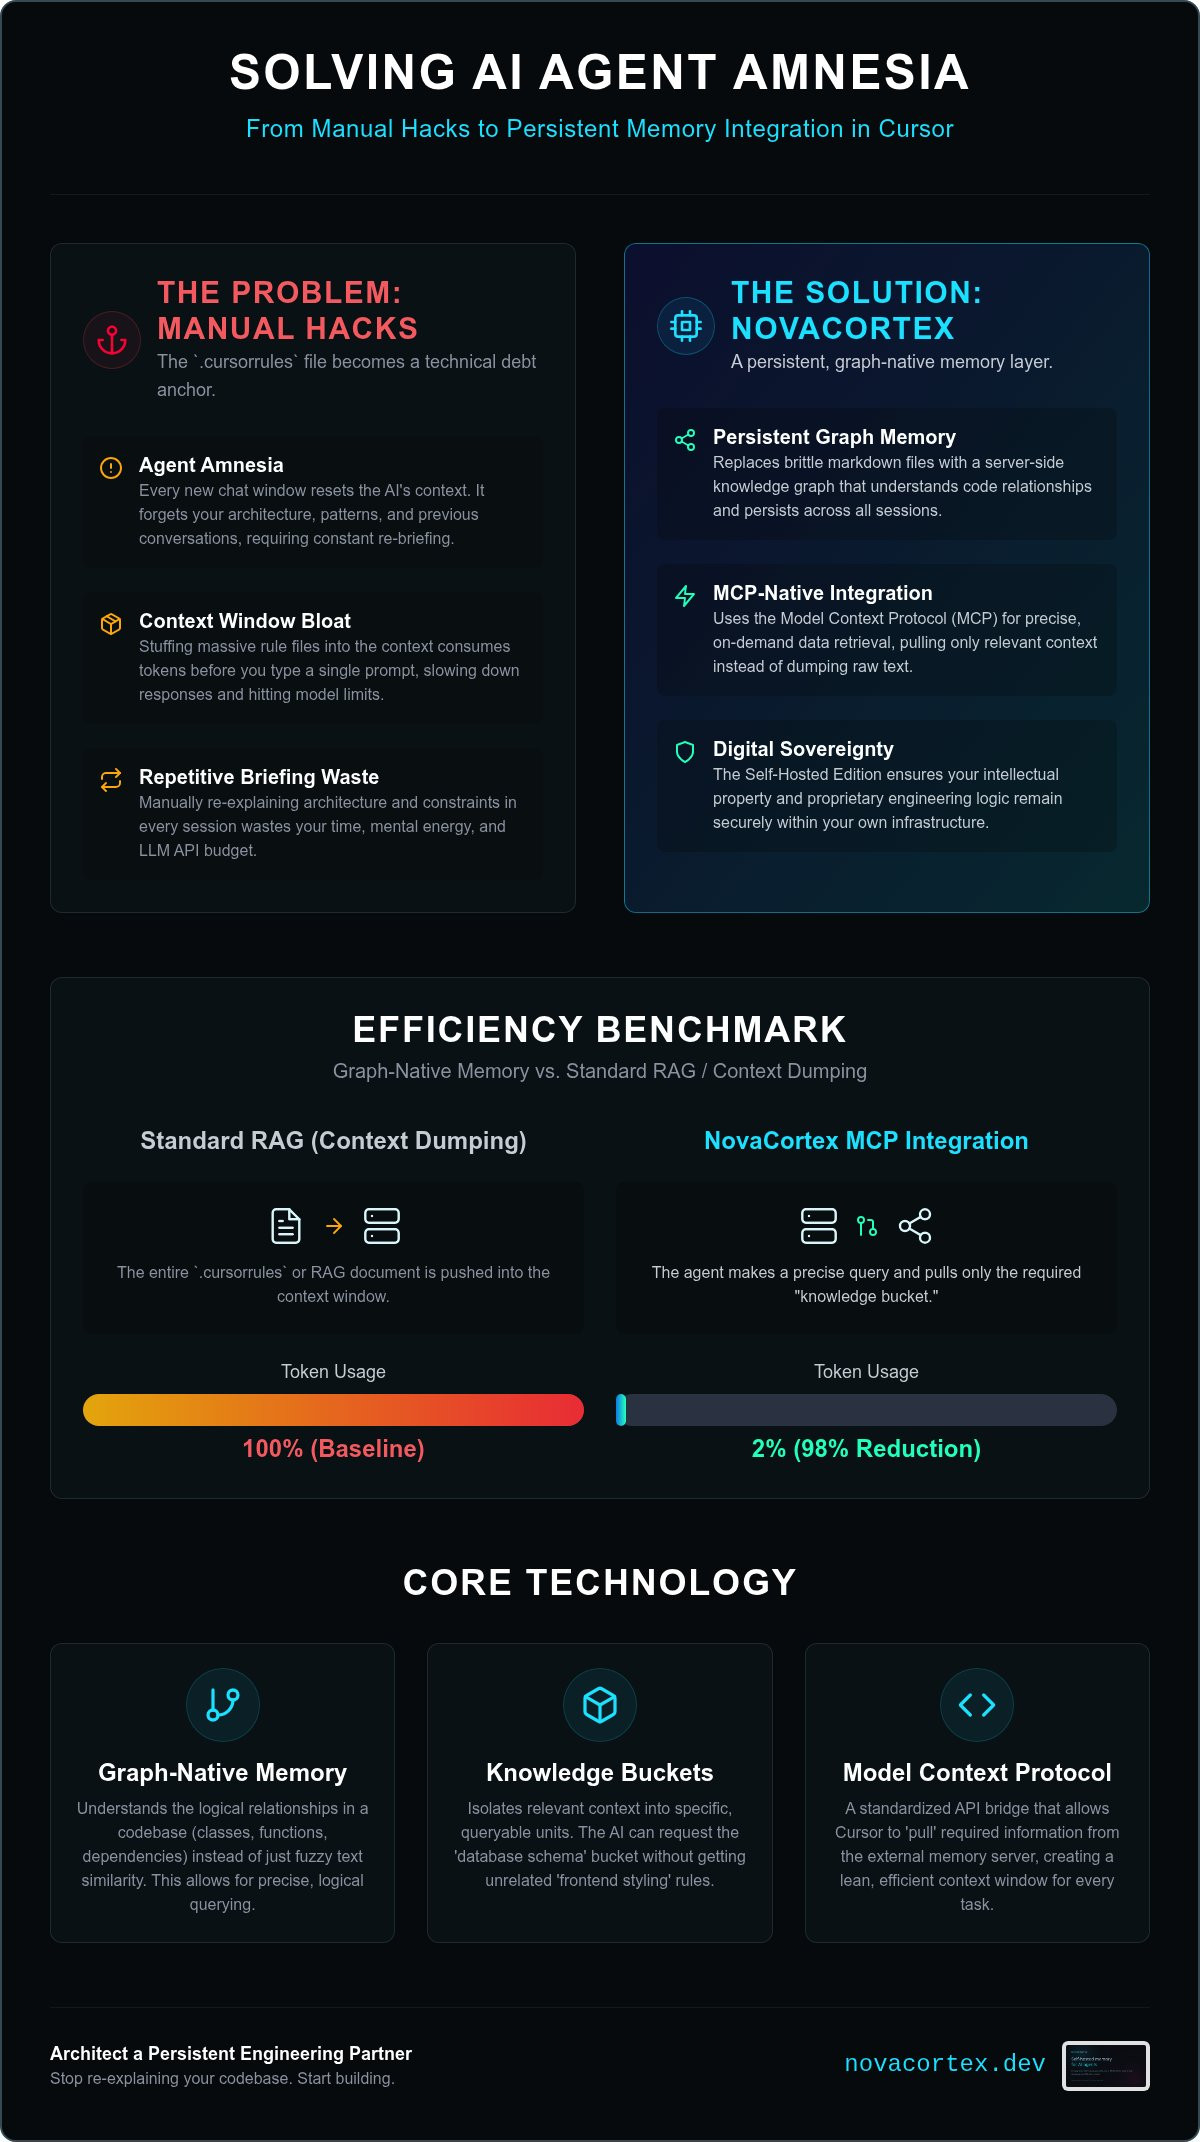
Your 500-line .cursorrules file isn't a strategy; it's a technical debt anchor. While it serves as a temporary patch, it inevitably leads to context window bloat and the agent amnesia that plagues every new chat window. Achieving a professional Cursor AI memory integration requires moving past these manual hacks and toward a persistent, graph-native infrastructure. You're likely tired of repetitive architectural briefings that waste both your time and your token budget.
We agree that current industry inefficiencies shouldn't dictate your workflow. This article blueprints how to architect an MCP-native memory layer that ends context loss and secures your digital sovereignty. You'll learn to deploy the NovaCortex Self-Hosted Edition to achieve 98% token efficiency compared to standard RAG. This briefing moves rapidly from identifying systemic waste to providing a technical resolution that transforms Cursor into a persistent, knowledge-aware engineering partner. It's time to stop re-explaining your codebase and start building with a tool that actually remembers your work.
Key Takeaways
- Eliminate agent amnesia by replacing brittle markdown files with a persistent, graph-native memory layer.
- Slash LLM API overhead with a 98% token reduction using Knowledge Buckets that isolate relevant context instead of dumping raw text.
- Implement a professional Cursor AI memory integration via the Model Context Protocol (MCP) to maintain architectural context across every session.
- Secure your intellectual property and engineering logic through the NovaCortex Self-Hosted Edition, ensuring absolute digital sovereignty.
Stop the Amnesia: Why Cursor AI Forgets Your Architecture
Every time you open a new chat window in Cursor, you're effectively resetting your agent's IQ to zero. This isn't a glitch; it's a fundamental architectural constraint. Despite the advancements in Cursor 2.0, the underlying Large Language Models (LLMs) operate on a stateless protocol. They don't possess a native, persistent awareness of your specific design patterns, naming conventions, or previous debugging sessions. This leads to "Agent Amnesia," a state where the AI requires a fresh briefing for every new task. To solve this, developers need a robust Cursor AI memory integration that functions as an external cognitive drive.
Modern AI infrastructure is designed for high-throughput inference, not long-term retention. When a session ends, the context window is purged. Many engineers attempt to bypass this by stuffing project history into .cursorrules files. This is the "Context Bloat" trap. Massive rule files consume precious tokens before you've even typed a single character of code. They slow down response times and eventually exceed the model's effective attention span. It's an inefficient stopgap that fails to scale as your codebase grows.
The High Cost of Repetitive Briefing
Re-explaining your architecture is a hidden tax on your productivity. If you spend 200 tokens every session just to remind the agent that you're using a specific repository pattern or a custom auth middleware, those costs compound. It's not just the API bill; it's the mental reload penalty. You're forced to act as a manual context manager rather than a lead architect. Manual "Memory Banks" or markdown-based logs quickly become unmanageable technical debt. They fall out of sync with the actual code, leading the agent to hallucinate based on outdated documentation.
Stateless Chats vs. Persistent Engineering Cognition
The standard chat-loop is a linear, disposable interaction. Real engineering requires AI agent long term memory that persists across the entire project lifecycle. A persistent memory layer lives outside the IDE session, serving as a source of truth that remains constant even as you switch between chat windows or different branches. We are seeing a necessary transition from file-based hacks to server-side integrations. By moving memory to a dedicated server, you ensure that your agent's knowledge is graph-native and instantly retrievable. This shift is the only way to achieve true engineering persistence without the bloat of legacy context-loading methods.
Beyond Markdown Files: The Case for MCP-Native Memory Servers
Markdown files are a legacy stopgap. While projects like cursor-memory-bank attempt to persist knowledge, they rely on static hierarchical text. This approach is inherently brittle. It lacks relational querying. It forces the agent to parse entire files just to find a single architectural rule. For a high-velocity Cursor AI memory integration, you need a system that understands the logic of your code, not just the keywords. This is where the Model Context Protocol (MCP) fundamentally changes the architecture of your development environment.
The Model Context Protocol acts as a standardized bridge between Cursor and external tools. It replaces the "context dumping" method with a precise retrieval system. By integrating an MCP native memory server, you provide your agent with a dedicated cognitive layer. This allows the AI to query specific knowledge buckets dynamically. It's the difference between handing an engineer a 500-page manual and giving them a searchable, interconnected database. The efficiency gains are immediate and measurable.
What is an MCP Memory Server?
An MCP memory server is an external service that Cursor communicates with using a standardized API. Instead of "pushing" every rule into the prompt, the agent "pulls" only what it needs for the current task. If you're working on a database migration, the agent pulls the schema history and migration patterns from the server. It ignores the unrelated frontend styling rules. This dynamic retrieval slashes token waste and keeps the context window lean. It moves the burden of memory from the LLM session to a dedicated, persistent infrastructure.
Graph-Native vs. Vector Search for Code
Standard vector search is insufficient for complex software engineering. Vector embeddings are fuzzy; they excel at finding similar text but fail to map the rigid, logical relationships of a codebase. Software is a graph. It consists of interconnected nodes like classes, functions, and dependencies. A graph-native approach preserves these relationships, allowing the agent to follow logic paths during retrieval. In the Redis vs graph memory for AI agents debate, graph storage is the clear winner for architectural persistence. It enables multi-hop reasoning that flat vector databases simply cannot match. For those looking to implement this level of precision, the open-source foundation of NovaCortex provides a robust starting point.
Benchmarking Efficiency: Graph-Native Memory vs. Context Dumping
Traditional RAG is a blunt instrument. Most developers settle for "context dumping," where they force the LLM to sift through thousands of lines of irrelevant markdown or vector noise. This practice creates a massive "Token Tax." You're paying for the model to process data that has zero impact on the current task. A professional Cursor AI memory integration requires a more surgical approach. By utilizing graph-native storage, you map the exact relationships between logic blocks, dependencies, and business rules. This architectural precision allows for a documented 98% token reduction compared to standard RAG. You stop subsidizing model provider profits with wasted context and start running a lean, high-velocity operation.
The technical foundation for this efficiency is the Portable Memory Format (PMF). PMF isn't just a storage container; it's a protocol designed for high-performance data transfer. It ensures that the communication between your memory server and Cursor remains structured and minimal. By moving away from bloated text files and toward PMF-encoded graph nodes, you ensure that every token sent to the LLM carries maximum information density. This is the difference between an unorganized pile of notes and a high-speed data bus.
Eliminating the Knowledge Dump
Irrelevant data is a cognitive toxin for LLMs. When you dump a massive project history into a chat, the model's attention is diluted, increasing the risk of hallucinations. Precision retrieval solves this by fetching only the specific graph nodes needed for the current file. Knowledge Buckets are modular units of specialized agent context. They isolate architectural domains, ensuring the agent only accesses the logic relevant to the immediate problem. This modularity prevents context window saturation and keeps the agent's focus sharp on the task at hand.
Latency and Performance Benchmarks
Engineering performance isn't just about token counts; it's about milliseconds. Cloud-based memory APIs introduce a round-trip latency that shatters a developer's flow state. Every time the agent has to wait for a remote server to "remember" a rule, your productivity stalls. Local MCP retrieval happens at machine speed. This low-latency response is critical for Cursor's "Composer" mode. When the agent is making rapid, iterative changes across multiple files, it needs an instantaneous memory layer. A local Cursor AI memory integration keeps your development loop tight and your "Composer" sessions responsive. High-latency systems are a bottleneck; graph-native local servers are a force multiplier.
Step-by-Step: Integrating NovaCortex Memory with Cursor AI
Deploying a professional Cursor AI memory integration requires moving beyond the IDE's default settings. You need a dedicated service to handle the architectural persistence layer. First, ensure you have Cursor installed and a local instance of the NovaCortex Self-Hosted Edition operational. This local instance acts as your private cognitive server. It keeps your intellectual property and engineering logic on your own hardware, ensuring absolute digital sovereignty from the start. Don't settle for cloud-based memory that leaks your proprietary patterns to third-party providers.
The Model Context Protocol (MCP) serves as the industry-standard bridge for this integration. It allows the IDE to communicate directly with your memory server. In Cursor, navigate to Settings > Models > MCP. Add your NovaCortex endpoint. For local development, this is typically your localhost address; for distributed teams, use your secure VPS endpoint. After adding the server, verify the connection immediately. You must see the active toolset listed, specifically query_memory and store_fact. These tools allow the agent to read from and write to your graph-native storage without manual file manipulation.
MCP Server Configuration in Cursor
Once the connection is live, initialize a project-specific Knowledge Bucket. Think of this as a dedicated partition for your current repository's logic. This isolation prevents cross-project context contamination. It ensures that when the agent queries for specific architectural patterns, it gets the implementation for the current stack, not a generic hallucination from a previous project. It's a modular approach that mirrors the way you structure your own codebases.
Teaching Cursor to Remember
The final step is establishing a rigorous "memory commitment" protocol. Use your .cursorrules file to define the triggers for storage. Instruct the agent to execute a tool call to store_fact whenever a major architectural decision is reached or a core service is refactored. You don't want a transcript of every typo; you want a record of engineering intent. When you open a new chat, the agent uses the query_memory tool to pull the relevant nodes from your Knowledge Bucket. It effectively remembers the state of the system before you type your first prompt. This ends the era of manual "memory bank" updates and repetitive briefings.
Digital Sovereignty: Self-Hosting Your Private AI Memory Layer
Digital sovereignty isn't a luxury. It's an engineering requirement. Professional Cursor AI memory integration demands absolute control over your data. Relying on cloud-based proprietary memory providers means surrendering your architectural logic to a third party. This creates a massive security surface area. It introduces a persistent risk of data leaks. To ensure absolute privacy, self-hosting your AI memory layer is the only viable path forward. The NovaCortex Self-Hosted Edition provides the infrastructure needed to keep your engineering cognition local and private. It moves memory from a third-party black box to a transparent, self-managed asset.
Ending Vendor Lock-in with PMF
Your knowledge is your competitive advantage. It shouldn't be trapped in a proprietary cloud database. The Portable Memory Format (PMF) ensures that your engineering knowledge remains as portable as your source code. PMF is a graph-optimized storage standard. It's built to break the cycle of vendor lock-in. By using a standardized format for your Cursor AI memory integration, you retain the ability to migrate your data between different models or environments. You don't lose context. This protocol structures complex relationships for maximum interoperability. It ensures your agent's memory evolves alongside your stack. Review the Portable Memory Format for AI technical specs to see how it handles high-density data transfer.
Enterprise Readiness and Security
Enterprise security requires more than just encryption at rest. It demands physical and logical isolation. You can deploy NovaCortex on a private VPS, a dedicated local server, or even a Raspberry Pi. This flexibility allows you to manage distinct Knowledge Buckets for different client projects. It prevents sensitive logic from one project from bleeding into the context of another. As you scale, multi-user controls allow you to share architectural memory across your entire engineering team. This creates a collective intelligence that grows with every commit. Moving toward a fully sovereign AI development environment isn't just about privacy. It's about building a resilient, independent engineering stack that you truly own. You're no longer just a consumer of AI. You're the architect of your own persistent intelligence.
Architecting Persistent Intelligence
Stop fighting against agent amnesia with legacy hacks. Static markdown files and bloated rule sets are architectural dead ends that drain your token budget and stall your momentum. A professional Cursor AI memory integration requires moving to a graph-native, MCP-compliant infrastructure. By deploying a self-hosted memory layer, you secure a 98% token usage reduction and maintain absolute ownership of your engineering logic. This approach replaces wasteful context dumping with precision retrieval, ensuring your agent acts as a true architectural partner rather than a stateless assistant.
This shift isn't just about efficiency; it's about building a sovereign development environment. Utilizing Apache-2.0 open-source foundations ensures your stack remains independent, portable, and high-velocity. You now have the technical blueprint to engineer persistent cognition into your daily workflow. It's time to move past the limitations of standard IDE chats and build with a memory layer that respects your time and your data sovereignty.
Take command of your development lifecycle and let your agent finally remember the complex architecture you've worked so hard to build.
Frequently Asked Questions
How does Cursor AI memory integration differ from using .cursorrules?
Cursor AI memory integration replaces the static bloat of .cursorrules with dynamic retrieval. While rule files force the LLM to process every line in every session, an MCP-native server only provides the specific context requested. This prevents context window saturation and reduces technical debt. It moves the burden of knowledge from a local markdown file to a persistent, graph-native infrastructure that scales alongside your codebase without wasting tokens.
Can I use NovaCortex with other IDEs besides Cursor?
Yes, NovaCortex is built on the open Model Context Protocol (MCP) standard. This means any IDE or agentic tool that supports MCP can connect to your memory server. While Cursor is a primary use case, you can integrate your Knowledge Buckets with other compatible environments. This flexibility ensures your engineering cognition isn't locked into a single tool, maintaining your digital sovereignty across different development platforms.
Does a self-hosted memory server require a GPU?
No, running the NovaCortex Self-Hosted Edition does not require a GPU. The server manages graph-native storage and retrieval logic, which is CPU-efficient and has a low memory footprint. You can deploy it on standard hardware like a VPS, a local server, or even a Raspberry Pi. It functions as a specialized, high-performance database for your agent's context rather than a heavy LLM inference engine or model host.
How does graph-native memory reduce my LLM token costs?
Graph-native memory reduces costs by eliminating the "Token Tax" of irrelevant context. Instead of dumping raw text into the prompt, the system uses Knowledge Buckets to isolate and retrieve only the specific nodes relevant to your current task. This surgical precision leads to a 98% reduction in token usage compared to standard RAG. You only pay the model to process information that actually matters for the specific logic you're currently engineering.
Is my code safe when using an MCP-native memory server?
Your code is significantly safer with a self-hosted MCP-native server than with cloud-based alternatives. Because you own the infrastructure, your proprietary architectural patterns and logic stay within your private network. NovaCortex doesn't send your data to third-party memory providers. This setup ensures absolute digital sovereignty and protects your intellectual property from being used to train external models or leaking through the vulnerabilities of a managed cloud memory service.
What happens if I want to migrate my memory to another provider later?
Migration is seamless thanks to the Portable Memory Format (PMF). We designed PMF specifically to break the vendor lock-in cycle common in the AI industry. Your engineering knowledge is stored in an open, structured format that you can export or move to any other PMF-compliant system. You aren't tethered to a specific service. Your agent's memory remains as portable, independent, and secure as your original source code.
Can I share a Cursor memory bank with my entire development team?
Yes, you can scale your Cursor AI memory integration across a team. The system allows you to manage Knowledge Buckets that serve as a shared architectural truth for multiple developers. Multi-user controls and centralized hosting on a VPS or local server enable your entire team to contribute to and benefit from a collective engineering memory. This synchronizes architectural decisions across the organization, ensuring everyone builds on the same persistent context without manual updates.
Does NovaCortex support local LLMs like Ollama or Llama 3?
NovaCortex is entirely model-agnostic. It works with any LLM that Cursor or other MCP-compatible tools use, including local models like Llama 3 running via Ollama. The memory layer functions independently of the inference engine. Whether you're using high-end cloud models or fully local, air-gapped LLMs, the graph-native retrieval system provides the same persistent context. It ensures architectural awareness regardless of which specific model is processing your current request.
FAQ
What is an MCP Memory Server?
An MCP memory server is an external service that Cursor communicates with using a standardized API. Instead of "pushing" every rule into the prompt, the agent "pulls" only what it needs for the current task. If you're working on a database migration, the agent pulls the schema history and migration patterns from the server. It ignores the unrelated frontend styling rules. This dynamic retrieval slashes token waste and keeps the context window lean. It moves the burden of memory from the LLM session to a dedicated, persistent infrastructure.
How does Cursor AI memory integration differ from using .cursorrules?
Cursor AI memory integration replaces the static bloat of .cursorrules with dynamic retrieval. While rule files force the LLM to process every line in every session, an MCP-native server only provides the specific context requested. This prevents context window saturation and reduces technical debt. It moves the burden of knowledge from a local markdown file to a persistent, graph-native infrastructure that scales alongside your codebase without wasting tokens.
Can I use NovaCortex with other IDEs besides Cursor?
Yes, NovaCortex is built on the open Model Context Protocol (MCP) standard. This means any IDE or agentic tool that supports MCP can connect to your memory server. While Cursor is a primary use case, you can integrate your Knowledge Buckets with other compatible environments. This flexibility ensures your engineering cognition isn't locked into a single tool, maintaining your digital sovereignty across different development platforms.
Does a self-hosted memory server require a GPU?
No, running the NovaCortex Self-Hosted Edition does not require a GPU. The server manages graph-native storage and retrieval logic, which is CPU-efficient and has a low memory footprint. You can deploy it on standard hardware like a VPS, a local server, or even a Raspberry Pi. It functions as a specialized, high-performance database for your agent's context rather than a heavy LLM inference engine or model host.
How does graph-native memory reduce my LLM token costs?
Graph-native memory reduces costs by eliminating the "Token Tax" of irrelevant context. Instead of dumping raw text into the prompt, the system uses Knowledge Buckets to isolate and retrieve only the specific nodes relevant to your current task. This surgical precision leads to a 98% reduction in token usage compared to standard RAG. You only pay the model to process information that actually matters for the specific logic you're currently engineering.
Is my code safe when using an MCP-native memory server?
Your code is significantly safer with a self-hosted MCP-native server than with cloud-based alternatives. Because you own the infrastructure, your proprietary architectural patterns and logic stay within your private network. NovaCortex doesn't send your data to third-party memory providers. This setup ensures absolute digital sovereignty and protects your intellectual property from being used to train external models or leaking through the vulnerabilities of a managed cloud memory service.
What happens if I want to migrate my memory to another provider later?
Migration is seamless thanks to the Portable Memory Format (PMF). We designed PMF specifically to break the vendor lock-in cycle common in the AI industry. Your engineering knowledge is stored in an open, structured format that you can export or move to any other PMF-compliant system. You aren't tethered to a specific service. Your agent's memory remains as portable, independent, and secure as your original source code.
Can I share a Cursor memory bank with my entire development team?
Yes, you can scale your Cursor AI memory integration across a team. The system allows you to manage Knowledge Buckets that serve as a shared architectural truth for multiple developers. Multi-user controls and centralized hosting on a VPS or local server enable your entire team to contribute to and benefit from a collective engineering memory. This synchronizes architectural decisions across the organization, ensuring everyone builds on the same persistent context without manual updates.
Does NovaCortex support local LLMs like Ollama or Llama 3?
NovaCortex is entirely model-agnostic. It works with any LLM that Cursor or other MCP-compatible tools use, including local models like Llama 3 running via Ollama. The memory layer functions independently of the inference engine. Whether you're using high-end cloud models or fully local, air-gapped LLMs, the graph-native retrieval system provides the same persistent context. It ensures architectural awareness regardless of which specific model is processing your current request.